The AI Hardware Race Accelerates: Groundbreaking Chips
Nvidia and Cerebras reveal next-gen AI hardware built for the era of trillion-parameter models, edge robotics, and ultra-fast inference.
Faraz drives NovaLuna’s strategy for AI models and emerging innovations, shaping the future of intelligent systems.
The Next Frontier in AI Compute
AI hardware is no longer just about speed—it’s about scale, architecture, and specialization. At GTC 2025, Nvidia and Cerebras Systems set a new benchmark by unveiling chips that promise to supercharge generative AI, real-time robotics, and high-efficiency inference. These developments mark a pivotal moment in the evolution of enterprise AI infrastructure.
Nvidia's Blackwell Ultra & Vera Rubin: Designed for the Trillion-Parameter Era
At the center of Nvidia’s GTC 2025 keynote were Blackwell Ultra and Vera Rubin, two chips tailored to the increasingly divergent demands of foundational model training and real-world deployment.
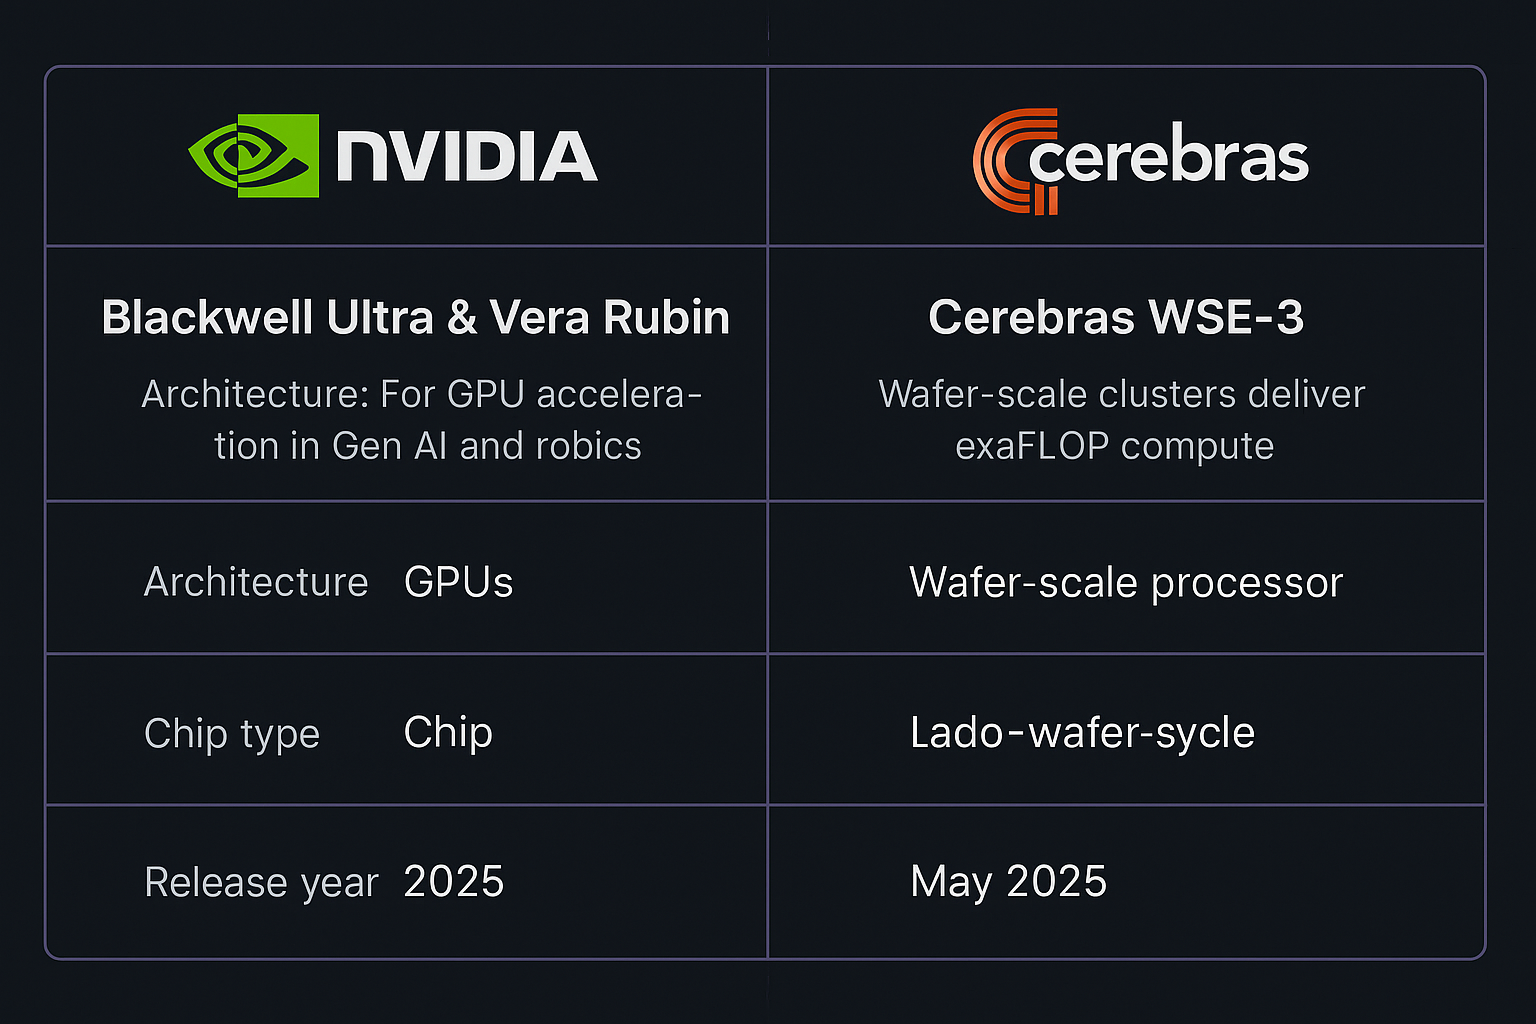
- Blackwell Ultra is Nvidia’s flagship GPU architecture built for hyperscale training. With its multi-die 3D stacking, it delivers >2x performance-per-watt versus Hopper and supports trillion-parameter transformer models.
- Vera Rubin, named after the astrophysicist who helped confirm dark matter, is a compact AI chip designed for real-time robotics. Its low-latency performance, neural processing cores, and integrated sensor fusion make it ideal for edge AI.
“These chips are not just faster—they’re purpose-built for the future of AI in both data centers and the physical world.”
— Jensen Huang, CEO of Nvidia
Cerebras: ExaFLOPs and GPU-Free Inference at Scale
In May 2025, Cerebras Systems made waves of its own by unveiling wafer-scale clusters capable of exaFLOP-level compute. Their unique architecture eliminates the interconnect bottlenecks of traditional GPU farms.
What sets Cerebras apart:
- WSE-3 Clusters: Entire silicon wafers acting as single chips, networked to create scalable AI supercomputers.
- Lightning-Fast Inference: Their new cloud-based inference service reportedly outpaces Nvidia’s top GPUs on 100B+ parameter models with lower latency.
- Turnkey IaaS: Enterprises can now access these capabilities via a new inference-as-a-service platform optimized for production LLMs and multi-modal applications.
Why This Matters for AI Teams and Enterprises
These announcements carry significant implications:
- For AI Teams: More compute options tailored to different stages of model development (training vs deployment).
- For Robotics Startups: Vera Rubin enables high-performance edge AI in power-constrained environments.
- For Enterprises Scaling Gen AI: Cerebras offers an alternative path to GPU scaling, with cost and speed advantages.
Visual Section Suggestion
Side-by-side graphic comparing Blackwell Ultra, Vera Rubin, and Cerebras Wafer-Scale Engine features and use cases.
Closing Thoughts
The AI hardware ecosystem is fragmenting—and that's a good thing. With Nvidia doubling down on specialized acceleration for model training and robotics, and Cerebras offering GPU-free alternatives for massive inference, enterprises have more strategic choices than ever.
At NovaLuna, we’re watching closely. As these chips hit production pipelines, expect to see a new generation of agentic AI tools, faster workflows, and innovations once bottlenecked by compute now brought to life.
Subscribe to our newsletter today
Get the latest insights on Generative AI, automation breakthroughs, and enterprise-ready LLM tools—delivered straight to your inbox.